Data engineering2025Paused6 min
Polymarket journey — part 1 of 3
To predict Polymarket outcomes, I first had to build the dataset
I set out to spot mispriced long-horizon markets on Polymarket. No public dataset had the history I needed, so I built the collector first, and learned that collection, not modelling, was the bottleneck.
- Role
- Research and systems engineer
- Timeline
- Months of work in 2025
- Stack
- Python, Pandas, Gamma API, Data API, CLOB
- Scope
- Data collection, holder features, dataset design
- Python
- Pandas
- Polymarket
- Gamma API
- Data API
- CLOB
- Data pipelines
- Feature engineering
- Question
- Could a model spot mispriced long-horizon binary markets on Polymarket before they resolved, using trade flow, the order book and who held each side?
- What I built
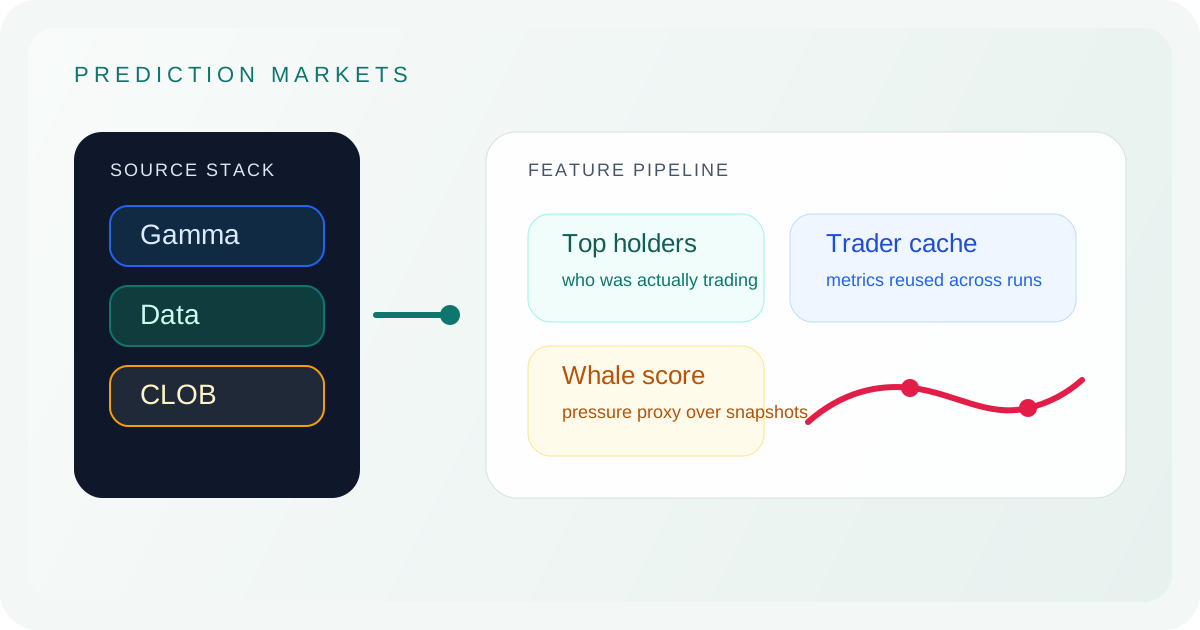
- A resumable collector over the Gamma API, Data API and CLOB, plus a holder layer that turned top holders and their wallet histories into features such as whale score and market lean.
- Outcome
- The pipeline worked, but building enough history cost more than the feedback it gave. I paused this front and carried its data lessons into faster loops.
I wanted to model who was trading, not only the price
This was the first phase of my Polymarket research, before the 15-minute bot and the HFT recorder. The question was the intuitive one: is a binary market mispriced before it resolves?
The thesis went beyond price prediction. Each market would be described by four families of signal:
- Trade flow: trades and price buckets from the Data API.
- Order book: spread, midpoint and depth from the CLOB.
- Market metadata: duration, category and volume.
- Holders: whale concentration, trader skill and which side the largest wallets leaned towards.
The fourth family was the ambitious one. It meant finding the top holders of each market and summarising the trading history behind their wallets.
There was no dataset to download
The first surprise came before any modelling. There is no public dump of Polymarket events with their full trade history, so every training example had to be assembled event by event: the Gamma API to discover events, the Data API for each market's trades, the CLOB for the order book.
Each event meant several requests, and any of them could hit a rate limit, a timeout or an identifier in a different format. Thousands of events meant hours, sometimes days, of collection.
If the dataset does not exist, data collection becomes the real project.
Five stages between an event and a training row
The collector was a Python package rather than a notebook: central config, bundle generators and separate outputs for training and inspection. Each stage is marked with how often it runs, and that is where the cost came from. Event discovery runs once per page; everything after it runs per market, and the holder layer adds wallet lookups on top.
01
Gamma API
Once per page of events
- Event and market metadata
- Paged scan, e.g. 100 per page
- initial_offset and min_volume_usd
02
Data API
Per market
- Trade history
- Trade flow and price buckets
03
CLOB
Per market, optional
- Book and midpoint
- Spread and depth
04
Top holders
Per market, optional
- Up to 20 holders (API cap)
- Trader metrics from wallet histories
- Cached for 5 days
05
Merge
TRAINING or LIVE mode
- features.csv
- raw_trades.csv, status.csv
- top_holders.csv, trader_metrics.csv
Wrapped around the whole flow: resume from the last processed event, a pause and retry on HTTP 429, and ID normalisation.
The holder layer turned wallets into features
Price history shows what the market believes. The optional holder layer tried to capture who stood behind that belief. It made the data richer, and collection even more expensive.
- Top holders
- Position concentration and holder mix for each market, up to the API cap of 20 holders (
top_holders_limit). Written totop_holders.csvfor inspection. - Trader metrics
- Trader-level statistics computed from wallet histories. Cached for 5 days and reused across runs, so repeated collections did not recompute the same wallets. Written to
trader_metrics.csv. - whale_score
- Whale influence in a market summarised into one number: a pressure proxy built from holder concentration.
- lean_yes_pct, lean_no_pct
- YES versus NO pressure among holders, weighted by whale score.
What looked easy on paper cost hours in practice
Feature ideas were never the blocker. The blocker was collecting enough history to trust the research, and every step that sounded simple had a price:
| On paper | In practice |
|---|---|
| Get historical markets | No public bulk dump. Every event meant several calls across Gamma, the Data API and the CLOB. |
| Scale the dataset | Page size, min_volume_usd filters and pagination offsets capped how many events one run could process. |
| Keep the scraper stable | 429 responses, retries, backoff and resume logic shaped runtime as much as the model did. |
| Add holder analytics | Wallet histories, top-holder reports and trader metrics made the data richer, and even more expensive to build. |
| Store the results | The CSV grew fast with all the price-bucket and checkpoint columns. |
A few thousand events could already take hours. Tens of thousands of clean examples meant many long runs, more storage and constant failure handling.
Six decisions that let multi-hour runs survive
Most of the engineering went into making collection restartable, cheap to repeat and safe to join.
01
Resume instead of restarting
Resume mode read the last
event_idwritten to the CSV, so an interrupted run continued from there instead of reprocessing events.resume from last event_id
02
Back off when the API pushes back
Rate limits were part of normal operation, not an edge case. An HTTP 429 meant a 5-second pause, then a retry with backoff.
HTTP 429 → 5 s pause
03
Normalise IDs before joining
Identifiers were inconsistent across endpoints (
conditionIdversus hexclobTokenIds). The collector normalised them to 0x-prefixed, 64-character hex so records from different endpoints lined up.0x + 64 hex characters
04
Keep scope in config
min_volume_usdandinitial_offsetlived in the config layer instead of the code, so each run could target a different slice of the market universe.min_volume_usd, initial_offset
05
Cache what is expensive to recompute
Trader metrics depend on wallet histories. Caching them for 5 days meant repeated runs did not waste calls rebuilding the same wallets.
trader-metrics cache: 5 days
06
One pipeline, two modes
execution_modeswitched betweenTRAININGandLIVE, so the same collection and feature code served both training and live-style scoring.execution_mode: TRAINING | LIVE
I paused it as a scope decision, not a verdict
The pause said nothing about prediction markets as a topic. Technically, the phase worked. Strategically, it was too expensive for the feedback it was giving me.
What worked
- An end-to-end collector across Gamma, the Data API and the CLOB
- Holder features that went beyond price history
- Five CSV outputs that made the research resumable and auditable
- A package layout and bundle tooling that later phases could reuse
What made it too expensive
- Long-horizon markets resolve slowly, so the learning loop was slow
- Coverage had to be broad enough to avoid training on a thin or biased slice
- The richer the dataset, the more collection became the bottleneck
- Tens of thousands of clean examples meant many long runs and a lot of babysitting
Own the data path first: the rule the next two phases inherited
This phase set the rule for everything after it: own the data path first, then decide whether the research deserves more time. Phase 2 moved to 15-minute markets, where the loop was much faster. Phase 3 stopped depending on history I had to scrape and recorded its own. The same realism mindset became How a real backtest works.
| Phase 1: long horizon | Phase 2: 15 minutes | Phase 3: HFT | |
|---|---|---|---|
| Data source | Scraped event by event from three APIs | Snapshots recorded continuously | My own 24-hour recorder, JSONL to Parquet |
| Feedback loop | Slow: markets take long to resolve | Much faster: 15-minute expiries | Second-scale windows |
| Where it landed | Paused: collection cost more than it taught | Stopped: expected value near zero after fees | Good classifier metrics, still negative maker-style PnL |
The package layout and bundle tooling from phase 1 mattered later, when the project had to become portable and server-friendly.
Related
Market systems2025–2026Stopped
Polymarket trading systems
Prediction-market research: a dataset builder, a 15-minute bot and a Rust + Python HFT recorder.
Latency and infrastructure
HFT on Polymarket: Rust, timestamps and the 98% hit rate that wasn't
Second-scale Polymarket research built recorder-first, with Rust on the hot path and LightGBM on top, and a 98% hit rate that fell to about 55% once latency was simulated.
Backtest realism
The backtest that lies, and the rules that stop it
The rules that keep short-horizon backtests honest: stop, take-profit, entry inside every bar, reaction latency, slippage, and payout and leakage audits.
Get in touch
Working on something similar? I am happy to compare notes.